AI Training & Application: From Dataset Creation to Model Deployment
AI training & application covers the full path from raw data to a working system. First, you build and label a dataset. Next, you train and tune a model with tools such as TensorFlow or PyTorch. Then you validate the results and deploy the model, often as an API service, so people and machines can use it. Each step depends on the one before it, and weak data usually leads to weak results. In this guide, I explain how the lifecycle works, where teams run into trouble, and how E.C.R Academy teaches these skills through project-based training.
Understanding the AI Training Lifecycle
What the Lifecycle Covers
Putting AI training & application to use, making the collection, training the model, and making sure it works are all steps that go together in my mind. To put together a dataset, you need to get raw data, clean it up, and label it so that a model knows what it is seeing. An algorithm learns to find patterns by being fed that data while it is being trained. It uses new data to test the model. This means that the model is put into a real process, like a web service or a camera station. And not just the modeling step. Teams should learn about all the steps in the process to get the most out of their time.
Why Data Work Takes Most of the Effort
A lot of people think it will be hard to write the model code. It turns out that's not true. The Google study from 2015 on secret technical debt talks about how the learning code is only a small part of a machine learning system in the real world. The rest is made up of machines that provide data, handle it, and set it up. The quality of the label is also important. There were label mistakes of 3.4% or more in the test sets of ten well-known standard datasets in a study from 2021. It is very important to be very careful with how you name things because they can get training and review wrong.
Where the Lifecycle Appears in Practice
There are three problems that businesses always have: bad data, not enough computer power, and trouble connecting a model to the tools and methods they use now. A group of people in a store could teach an object recognition model how to look for things on a shelf. This is one way that a farm technology team could use pictures to figure out what's going on with crops. It can only help if the data is like the real world, there is training gear, and the result can connect to a device or app that real people use. Because of this, our course covers the whole process, not just one step.
Dataset Creation: Practical Methods for Accurate Models
Designing the Business Data Workflow
I think they should make a map of the business process the AI will help with before taking a picture. Find out where the data comes from, who checks it, and what choice the model can help you make. A clear process finds holes quickly, like a step that doesn't have a boss or a source of data that has more than one form. This is the start of our course. Learners make a full system for gathering, organizing, and looking over data based on the needs of the business and the technology available. They use business analysis and workflow design tools to find weak spots in each module and suggest AI-based ways to make them better. Projects are always linked to a real need this way.
Collecting, Cleaning, and Annotating Data
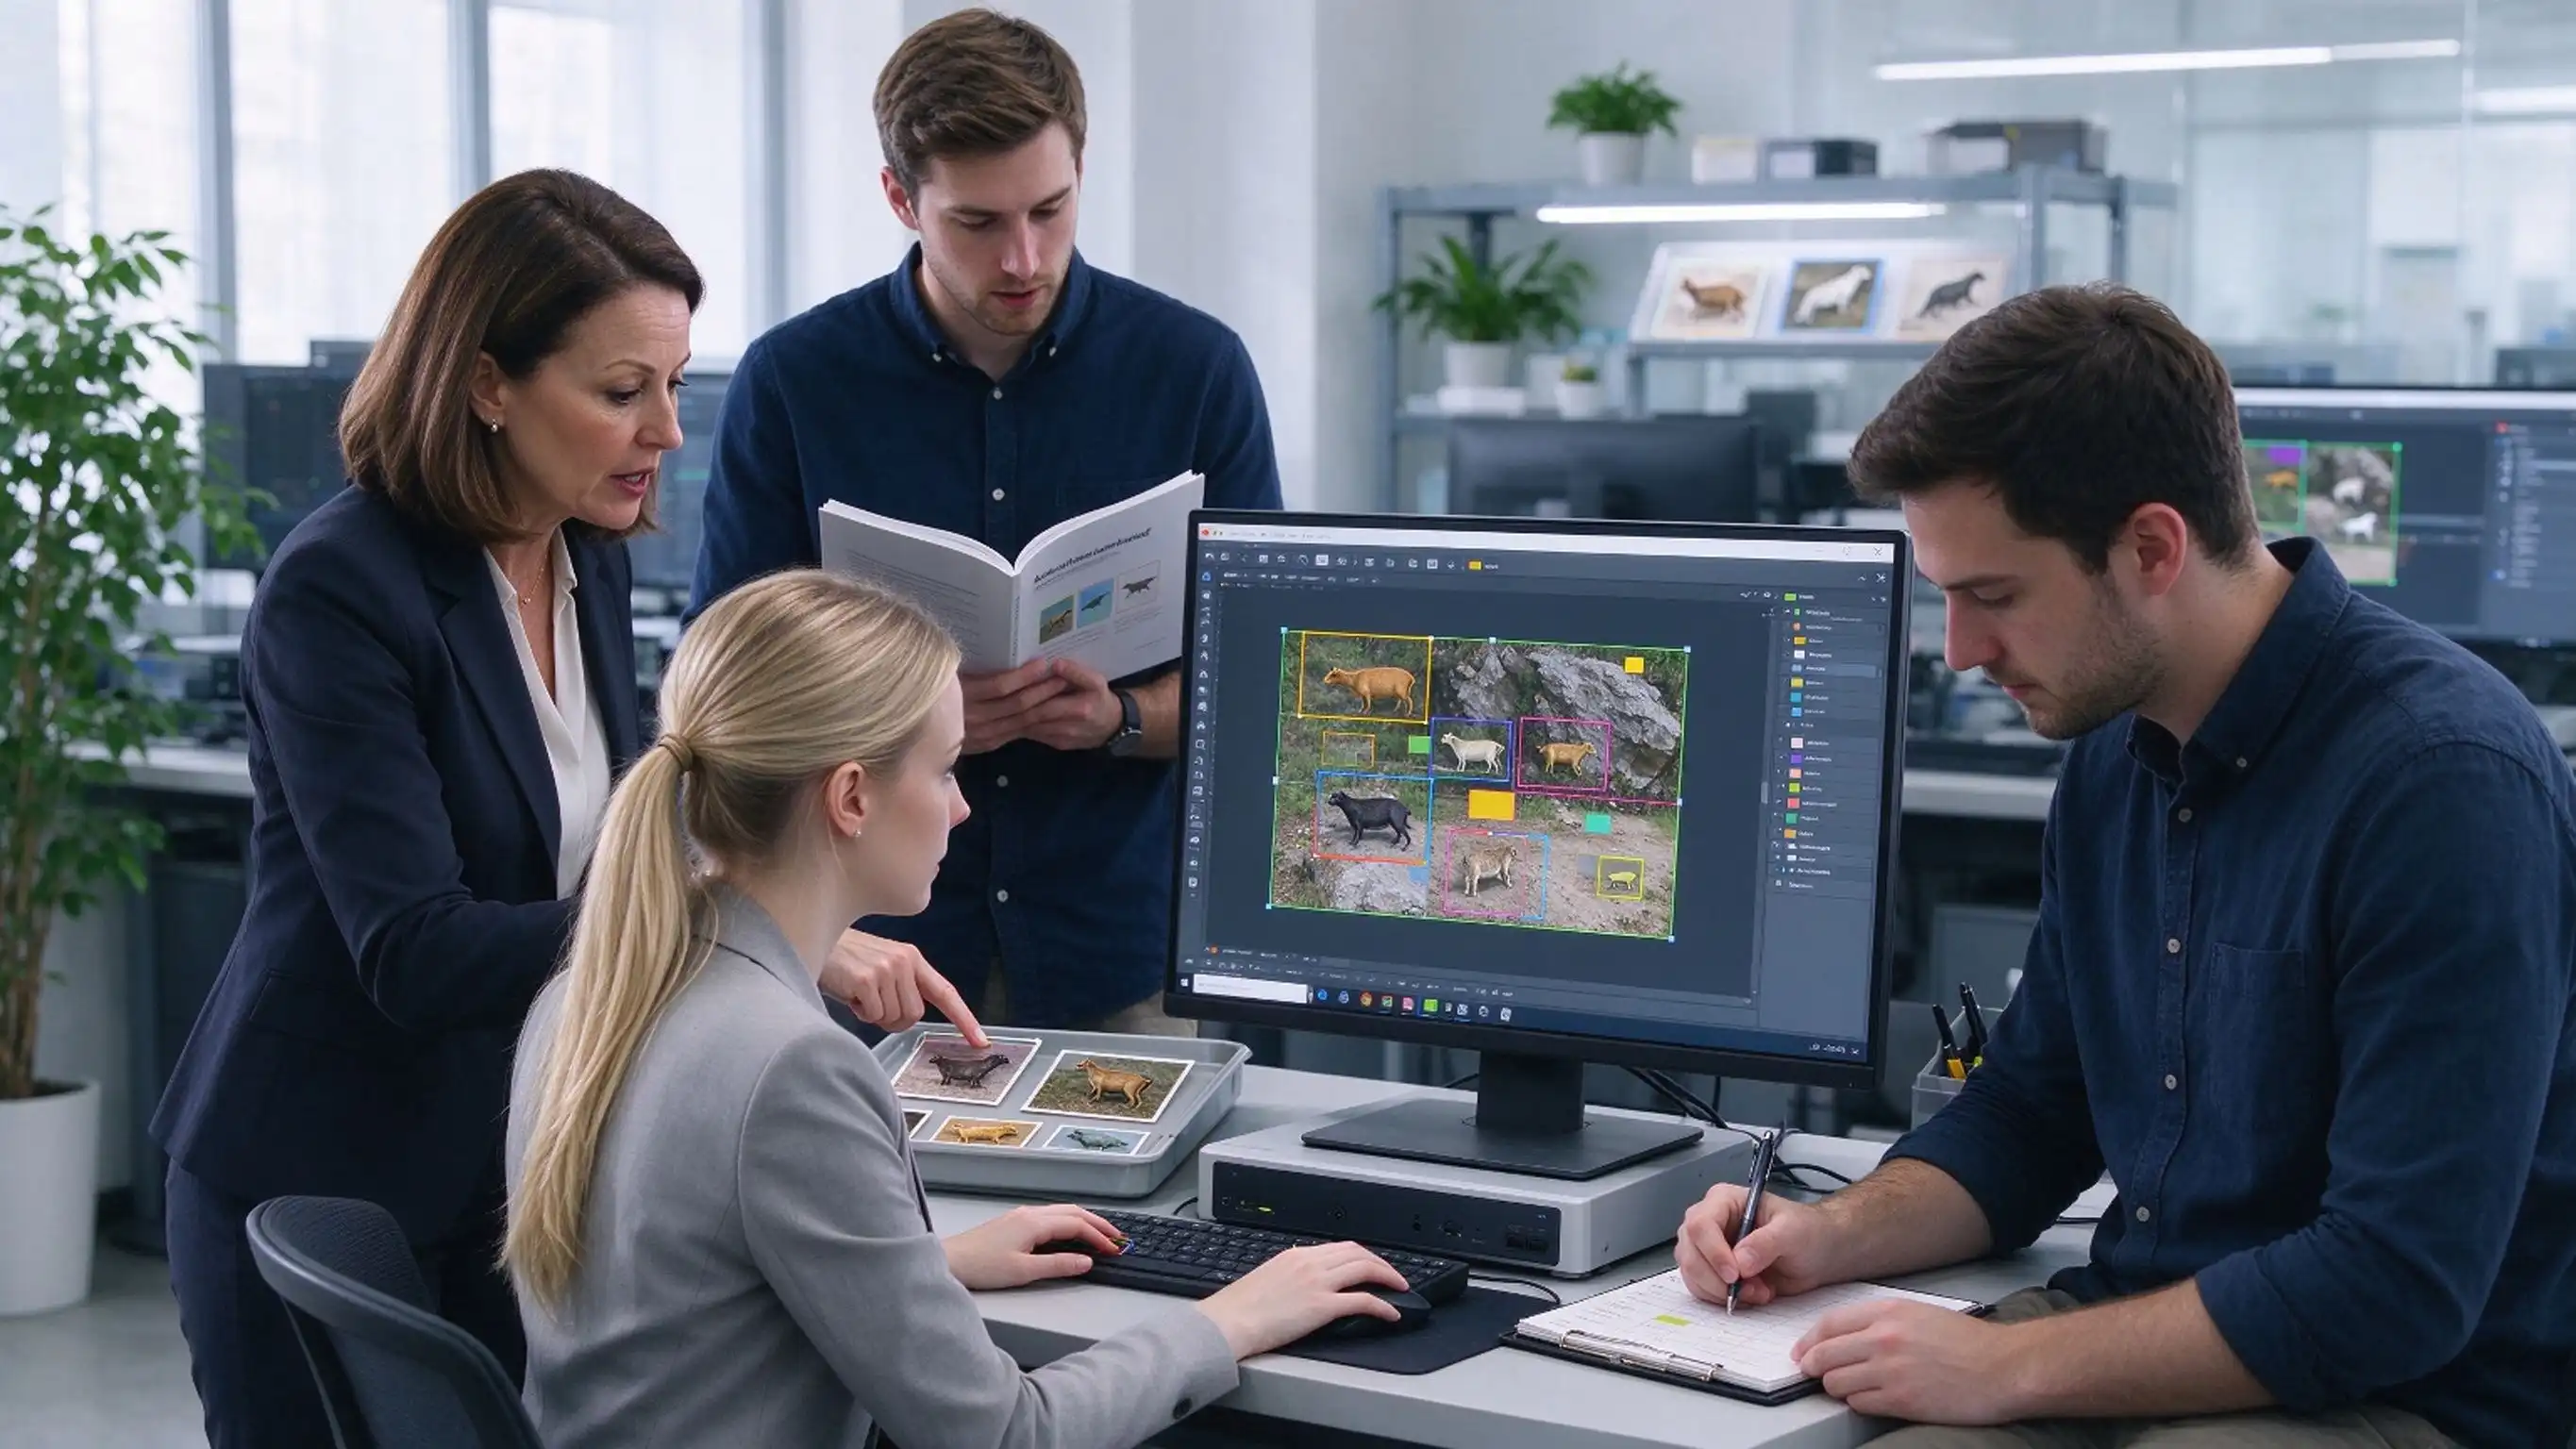
Good records stick to the rules that are written down. Collection should match the amount of light, camera angle, and products that will be used in the model. It gets rid of copies, blurry files, and things with the wrong names. Then, annotation adds class names or border boxes based on rules that all annotations must follow. This is a file that many teams use to store the results of object recognition. The idea for it came from the PASCAL Visual Object Classes Challenge. We teach our students how to make structured datasets in VOC format, name them according to rules, and manage the quality of the data on a site where people and AI can work together on annotations.
Privacy, Consent, and Dataset Management
Personal or sensitive data is often stored in datasets, so privacy needs to be taken into account when the data is being gathered. Before you collect any information, make sure you have permission and only what you need for the job. You should also look into the rules that apply, such as GDPR in Europe or the California Consumer Privacy Act in the US. The last word on compliance should come from your legal team. It is also good management to keep training and testing datasets separate, name versions clearly, and keep track of how each set was put together. Students learn how to keep and deal with both training and test files as part of our course.
Model Training: From Algorithm Selection to Tuning
Choosing Algorithms and Tools
Choose the right method for the job based on the amount of data that needs to be identified, the computer power you have, and the job itself. Deep learning models are often needed for image tasks like finding things in pictures. But normal machine learning techniques might work well for table situations that aren't too big. It's also important what tools you use for AI training & application. One well-known deep learning tool is TensorFlow, which was made at Google. The other is PyTorch, which was made at Facebook's AI research group, which is now called Meta. It is possible to use TensorFlow, Keras, PyTorch, Caffe, and more than 100 other libraries for machine learning algorithms on our platform. Students use models like YOLOv5 to help them figure out who they are.
Training Methods That Save Time
Three habits that help you train. During batch training, the model is given small groups of data at a time. So, the GPU doesn't use too much memory. Changes are made to a model that has already been trained on a large dataset so that it can do a new job. Most of the time, this means that less training time and labeled data are needed. When things change, you can keep a model up to date by training it again with new data. For our class, students bring in information, pick a model like YOLOv5, and change how it works. The platform gives them access to GPU computer power in the cloud, so they don't need to set up a complicated system on their own site.
Validating Accuracy and Fixing Errors
It is important to test models because they might work well on training data but not in real life. Cross-validation takes a set of data and picks a different part to use as the test set each time. You can get a better idea from this than from a single split. A/B testing lets you compare two versions of a model on real traffic after they have been put into use. It's also helpful to see what went wrong with the model and ask why. There are a lot of things that can go wrong, like labels that aren't clear or cases that are missing. The kids here use tools to figure out why mistakes happen and fix them. After that, one last test is done on the model before it is used.
Model Deployment: Integration and Real-World Operation
Choosing Between Cloud and On-Premise
Teams can quickly get to GPUs through cloud deployment, which also makes it easy to make changes. When teams use on-premise setup, they have full control over both the data and the tools. What many businesses use to decide what to do are things like data security, network quality, cost, and response time. When there is an urgent need for an answer at work, local hardware might work. But for a training class, sharing cloud resources would be best. Our learning platform has cloud-based GPU computing, so people can build and train models from anywhere without having to set up a computer at home. Partner should think about these trade-offs early on because they have an impact on the project's budget and its planning.
Deploying Models as API Services
If you use an API service, you can tell a model what to do and get a prediction back. This is how to call the same model from a computer page, a phone app, or a remote. This keeps the model separate from the apps that use it. This way, teams can change the model without having to write all the apps again. This is how our class is set up. They make an API service out of a learned model, make sure it works, and then write code to call it. Businesses also often move services from one machine to another using containerization, which groups software with all of its dependencies into one package.
Connecting AI to Hardware and Keeping It Running
When the model goes live, the work isn't done. People in our class who are working on building systems gather picture data, call model APIs, and run object recognition. The servos, indicator lights, and serial displays are all linked together. To send and receive control and data, they use protocols for serial communication. They also test the whole system, fix bugs, and make apps that are based on situations. Someone has to watch over a system so it can work. As time goes on, input data may become less similar to the training set, which makes the accuracy worse. This is fixed by having teams check the results often and make changes as needed.
Turning AI Training & Application into Job-Ready Skills
What E.C.R Academy's Course Teaches
We teach three skills in our course, which is based on the core competency model that AI trainers use for AI training & application.
- AI dataset creation: Learners collect and clean raw data, give pictures names that help people find things, order datasets in VOC format, and label things according to standards. Managing the quality of data and making datasets are skills that you will need later on in an AI project. These jobs give you real-world practice with these tasks.
- AI deep learning engineering applications: They bring in datasets, choose models like YOLOv5, change settings, and then look at the results. After that, they turn the model into an API service. When you use tools like TensorFlow and PyTorch on GPU resources in the cloud, these tasks help you get better at making models and tuning them.
- AI system assembly, adjustment, and operations maintenance: Learners take pictures, use model APIs, and do object recognition. The servos, indicator lights, and serial displays are all linked together. To send and receive control and data, they use protocols for serial communication. Being good at these jobs will help you build systems, fix bugs, and run things in your everyday life.
Students can see the whole process here, from the first picture that needs to be named to a system that is up and running.
The HD-AiLab Learning Environment
They are working on HD-AiLab V1.0, an all-in-one programming tool made by B/S that helps teach and train AI. It has an AI machine that does everything, a platform where people and AI can work together to mark data, a platform for algorithms, and a station for teaching AI how to use scenarios. You can use Python, R, Java, and C++ with it. A lot of machine learning algorithms and deep learning tools, such as TensorFlow, Keras, PyTorch, and Caffe, can be used with it. Plus, it comes with movies, papers, experiment code, and more than 5 TB of experimental data that is already added. The platform lets you teach, get certified, hold skill competitions, and look into new ideas.
Who Benefits and Which Roles It Supports
Business, school, industry, and other groups send people to make this course. The teachers have both worked as pros in the field and as teachers in other schools. The lessons are in line with how professional skills should be taught around the world. People who finish the training are ready to work as an AI trainer or data annotation specialist, an AI algorithm tester, an AI application development engineer, an AI system operations and maintenance engineer, or an AI application technician in smart agriculture and smart retail. Since 2010, E.C.R. Academy has taught and tested almost 500,000 people in China and 28 other countries. The group has also teamed up with more than 500 businesses.
Conclusion
As you design the process, make the dataset, train the model, test it, deploy it, and keep it running, everything in an AI training & application is connected. There is unpaid technical debt around the model, and label mistakes can be found even in well-known standard datasets. This is why it's important to work on the data as soon as possible. To protect the quality of the model, there are clear rules for annotations, privacy checks, and separate sets for training and testing. Transfer learning, cross-validation, error analysis, and the choice of algorithm and tool can all help make things more accurate. It's important for models to be able to be used outside of the lab. They should be able to be deployed in the cloud or on-premise, have API services, work with hardware, and be checked regularly. Crews can better plan jobs and learn skills that come in handy in real life when they know about each step.
FAQ
1.Can I take this course with zero prior knowledge?
Yes. The course builds on the last step. It starts with simple tasks like gathering data and labeling it. For new users, the one-stop website and the resources that come with it are helpful.
2.What prerequisite knowledge is recommended?
You should know how to use a computer and some Python code. The course then slowly moves on to deep learning and putting systems together.
3.How is the platform deployed?
It lets you use GPU computing resources in the cloud, so you don't have to set up a lot of things locally to build and train models. It's always open and accessible.
4.Which tools do learners use?
People in school use tools like TensorFlow, Keras, PyTorch, and Caffe. HD-AiLab V1.0 uses YOLOv5 for projects that need to find things.
5.What career positions does the course support?
As an AI trainer, data annotation specialist, algorithm tester, AI application development engineer, AI system operations and maintenance engineer, or AI application worker in a smart store or farm are all jobs that use AI.
Talk to E.C.R Academy About AI Training & Application
Comparing AI training & application providers for your school, company, or organization? The teachers at E.C.R Academy come from both business and academia, and the platform comes with built-in datasets and algorithm libraries. Send us an email at ecr2008@enteredu.com with your goals, team size, and schedule, and we'll talk about a fit. You can find out more at enteredu.com.
References
1. The Pascal Visual Object Classes (VOC) Challenge, International Journal of Computer Vision, 2010
2. Hidden Technical Debt in Machine Learning Systems, Advances in Neural Information Processing Systems, 2015
3. Pervasive Label Errors in Test Sets Destabilize Machine Learning Benchmarks, NeurIPS Datasets and Benchmarks Track, 2021
4. TensorFlow: A System for Large-Scale Machine Learning, USENIX OSDI, 2016
5. PyTorch: An Imperative Style, High-Performance Deep Learning Library, Advances in Neural Information Processing Systems, 2019
6. You Only Look Once: Unified, Real-Time Object Detection, IEEE CVPR, 2016